
01
Multi-Modal Document Parsing
Extracting tables, diagrams, headers, and unstructured text from PDFs, DOCX, scans, and spreadsheets.
Enterprise-grade Retrieval-Augmented Generation (RAG) pipelines. Ground your AI in verified proprietary company documents with sub-2% hallucination rates.
Every build is held to strict performance, security, and conversion benchmarks.
From custom application architecture to automated workflows and system integrations — engineered to solve your specific operational bottlenecks.
Extracting tables, diagrams, headers, and unstructured text from PDFs, DOCX, scans, and spreadsheets.
Combining dense vector embeddings with sparse keyword matching to find exact part numbers and conceptual meanings.
Re-ranking retrieved chunks with cross-encoder models so the LLM receives only the most accurate context window.
Every answer links directly to the source page, paragraph, and line number in the original document.
Enforcing role-based access controls (RBAC) so users only retrieve information their clearance level permits.
Real-time connectors to Google Drive, SharePoint, Notion, Jira, and SQL databases that update vector indexes on change.
Explore recent projects and case studies showcasing how we design, build, and scale solutions with Enterprise RAG & Search Engines.
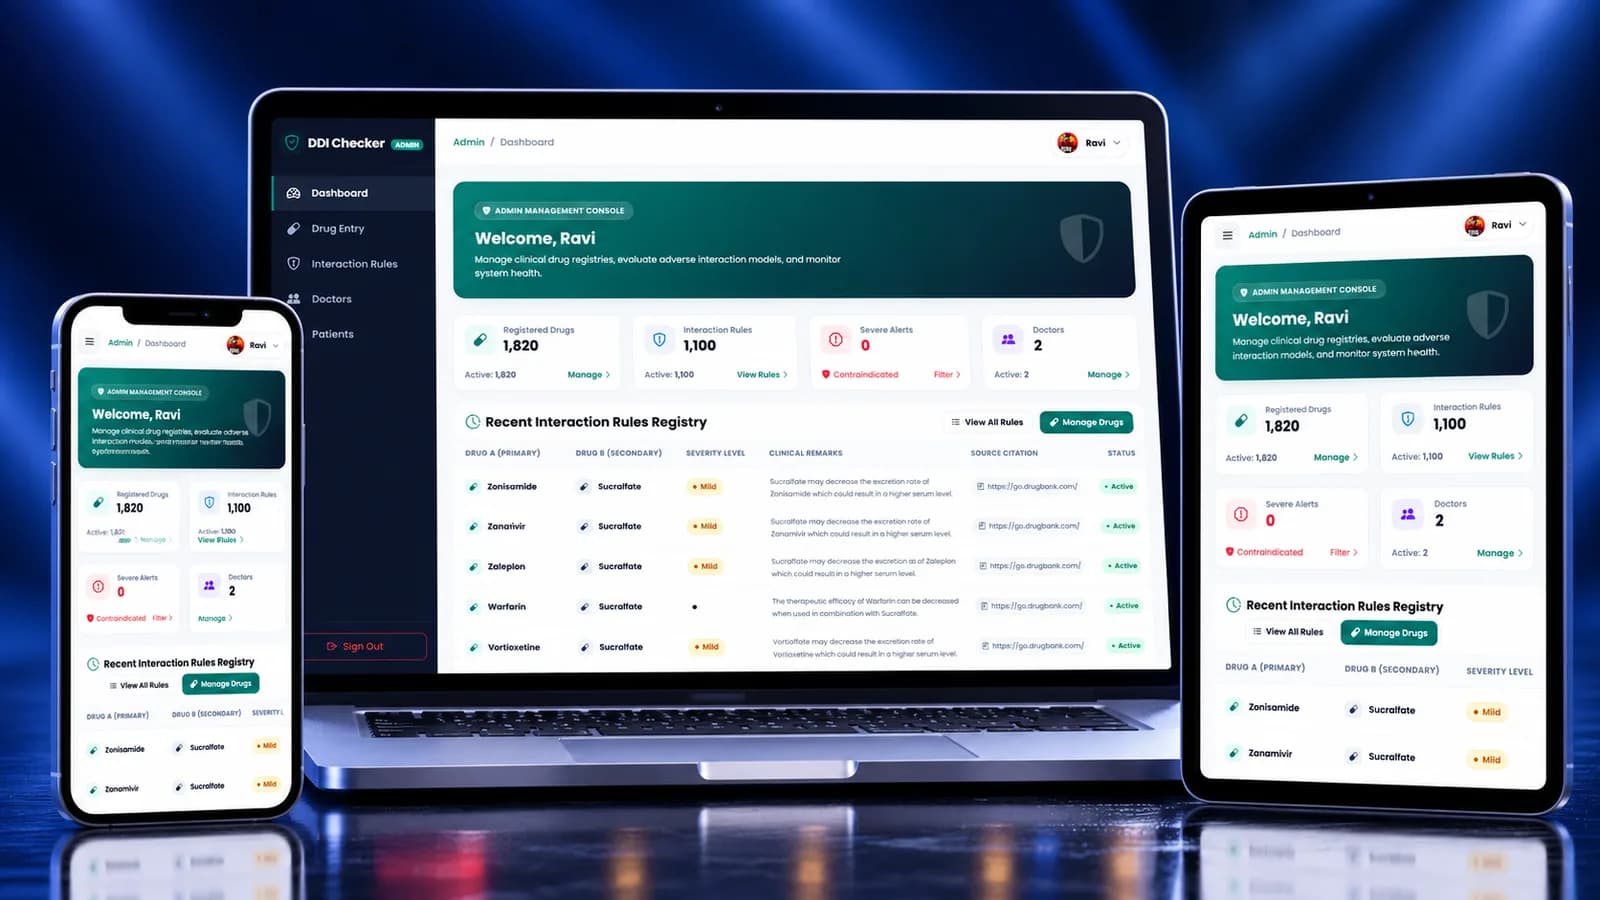
A clinical decision-support platform enabling doctors to build prescriptions with real-time drug-drug interaction alerts graded by clinical severity.
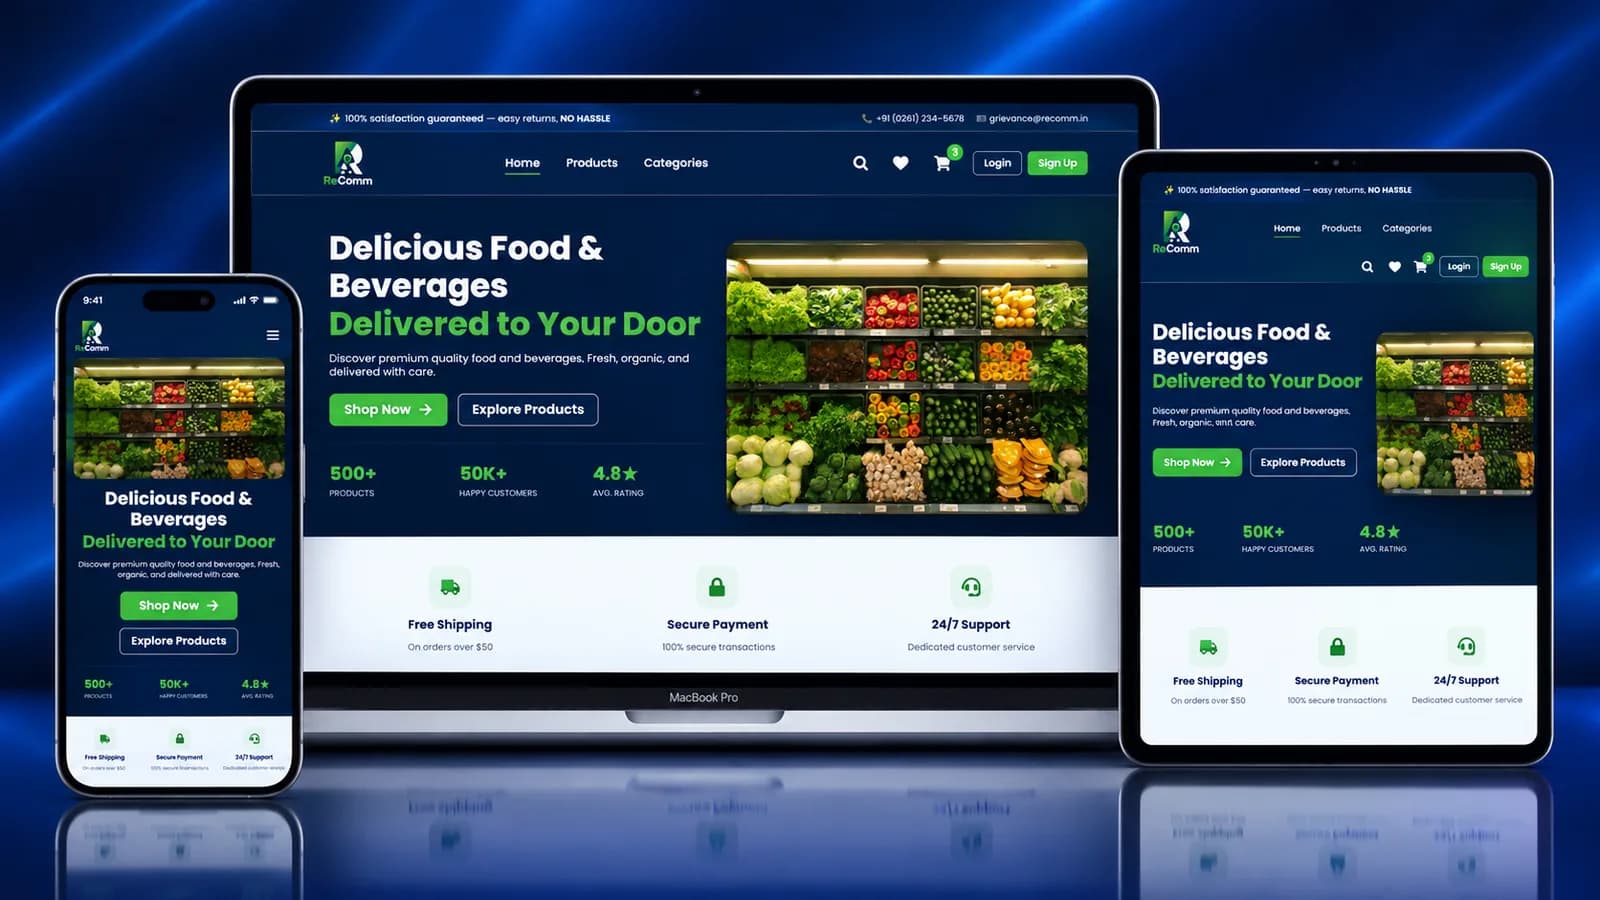
An enterprise hyperlocal multi-vendor marketplace platform connecting neighborhood merchants with digital consumers through real-time proximity discovery, dynamic road routing, and multi-slot delivery.
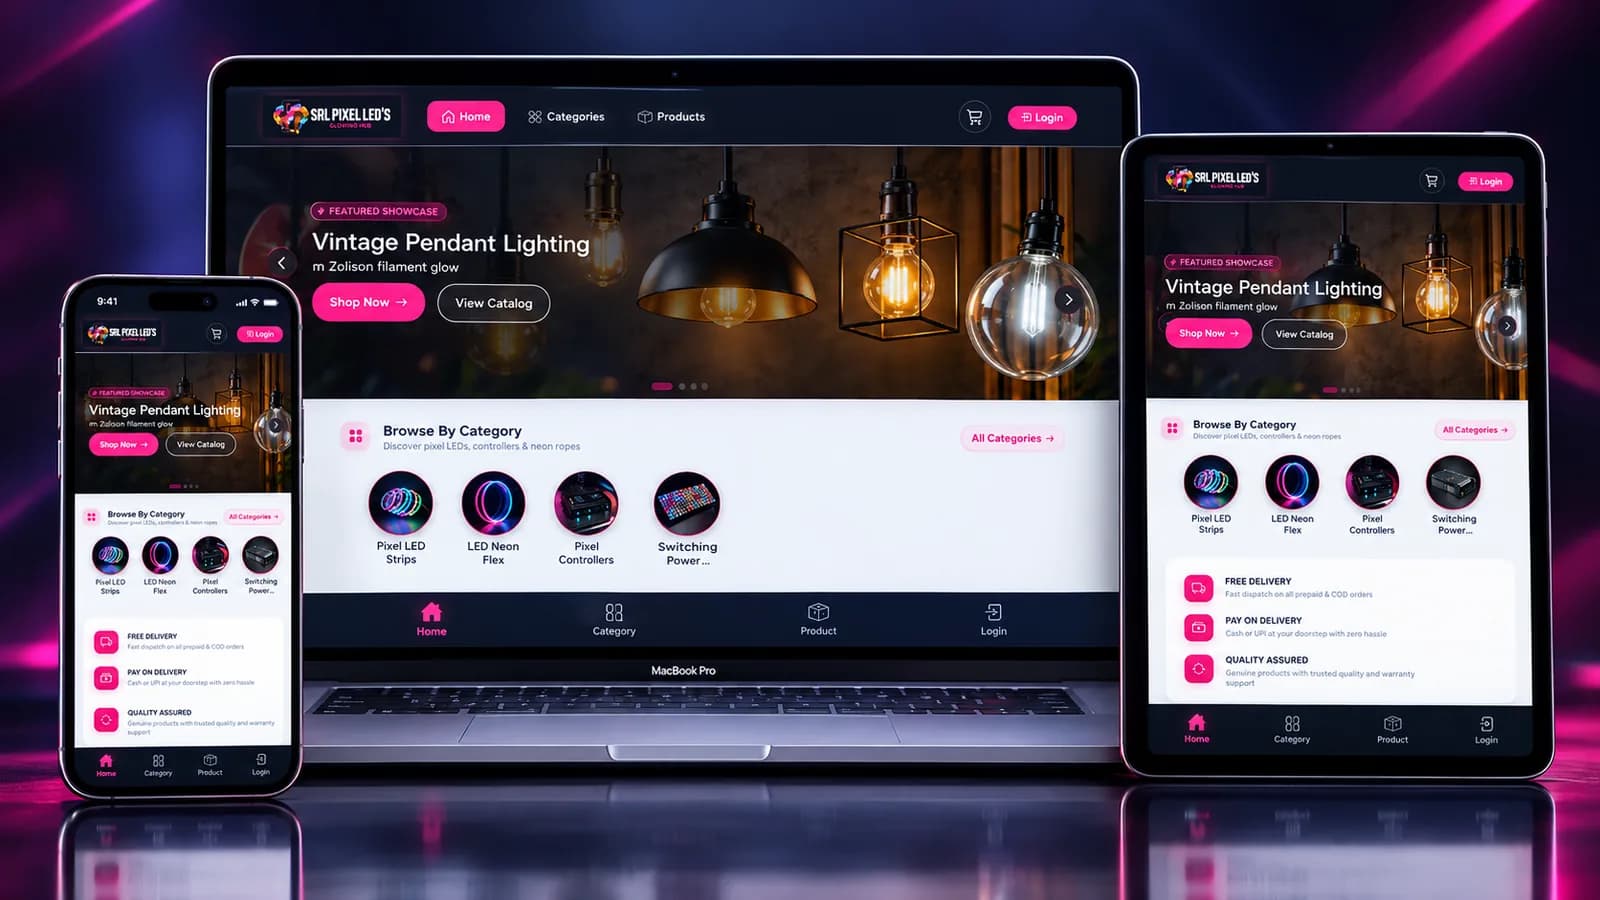
An Omnichannel E-Commerce & Retail POS Platform for Next-Generation Addressable LED Lighting and Controllers.
A battle-tested 4-step delivery pipeline combining strategic scoping, rapid prototyping, bi-weekly agile demos, and zero-downtime release.
Analyzing file formats, table complexities, and designing domain-tailored semantic chunking strategies.
Extracting embeddings with state-of-the-art models and populating high-dimensional vector databases.
Evaluating retrieval recall, Mean Reciprocal Rank (MRR), and eliminating hallucinations with synthetic test sets.
Deploying high-speed RESTful search APIs and interactive user chat interfaces with telemetry tracing.
We operate as your high-velocity engineering partner, committed to code ownership, sub-second performance, and measurable business impact.
If the requested fact is not in your documents, the system safely admits it rather than hallucinating false information.
Crucial for compliance, legal, medical, and financial use cases where answers must be verified against original source text.
Instantly locate specific alphanumeric SKUs, customer IDs, and legal clauses in under 250 milliseconds.
Your vector database and embedding pipelines operate within your own private virtual cloud.
Clear answers regarding project timelines, code ownership, technical security, and post-launch SLAs.
We enforce strict RAG architecture: context bounding, cross-encoder reranking, temperature minimization, and mandatory source citations matching real document chunks.
Yes, our document ingestion pipeline uses multi-modal vision parsers to accurately extract table grids, financial balances, and flowcharts into clean Markdown tables.
Integrate your technology stack with our complementary engineering and growth services.
Fast, scalable web apps and corporate platforms built with React, Next.js, Laravel, and headless architecture.
View SpecificationsHigh-converting online stores, Shopify Plus architectures, omnichannel POS integrations, and custom checkout flows.
View SpecificationsCross-platform iOS and Android apps with React Native, Flutter, and native-quality 60fps ergonomics.
View SpecificationsConnect directly with a lead solution architect. We'll evaluate your use case, provide an architectural feasibility blueprint, and scope realistic milestones.
All repositories, deployment scripts, and intellectual property transfer to your organization upon delivery.